For a Preply-scale tutoring marketplace, Statsig is usually the stronger choice for experimentation, while LaunchDarkly is stronger for controlled software releases. If the main goal is safer A/B testing across tutor search, onboarding, pricing, and lesson booking flows, Statsig fits the product analytics workflow better. If the main goal is reducing release risk through feature flags, approvals, kill switches, and staged rollouts, LaunchDarkly is hard to beat.
TLDR: Preply should treat feature flags and experiments as risk controls, not just growth tools. For example, a new tutor ranking model could be rolled out to 5% of learners, then expanded only if trial lesson bookings rise by 2% and refund requests stay flat. LaunchDarkly is better for safely shipping that model behind a flag; Statsig is better for measuring whether it actually improves the marketplace. A serious setup may use one primary platform, with strict rules to avoid split ownership of assignments and metrics.
Why safer experimentation matters for Preply
Preply is not a simple content site where a failed test only hurts click rates. It is a two-sided marketplace. A small product change can affect learner conversion, tutor visibility, lesson completion, support volume, and revenue quality at the same time.
That makes A/B testing risky when it is treated as a casual growth habit. A tutor search experiment might improve bookings for new learners while reducing income for experienced tutors. A pricing test might lift checkout conversion but increase cancellations two weeks later. A faster onboarding flow may bring more signups but lower activation quality.
The safer pattern is simple: separate release control from experiment interpretation, then connect them through clean exposure logging, guardrail metrics, and rollback rules.
LaunchDarkly: best when release safety comes first
LaunchDarkly is built around feature management. Its strongest value is giving engineering teams precise control over who sees a feature, when they see it, and how fast rollout grows.
For Preply engineering, that matters in areas such as:
- Tutor search ranking: release a new ranking service to internal staff, then 1%, 5%, and 25% of learner traffic.
- Booking flow changes: turn off a new checkout component if payment errors increase.
- Mobile app releases: hide unfinished features without waiting for app store review cycles.
- Operational incidents: disable a recommendation module without redeploying backend services.
LaunchDarkly also fits mature engineering processes. Audit logs, role-based access, approval workflows, flag history, and environment separation make it easier to run experiments inside a controlled release process. This is useful in a company where product, data, engineering, mobile, and operations teams all touch the same user flows.
The catch is that LaunchDarkly’s experimentation features can feel secondary if the team wants deep statistical workflows. You can run experiments, but the center of gravity stays with flags and rollout control. When analysts expect metric layers, automated diagnostics, cohort breakdowns, and experiment health checks, they may feel boxed in.
Statsig: best when experiment quality comes first
Statsig started closer to the experimentation problem. It combines feature gates, experiments, metric management, holdouts, and diagnostics in one product. That makes it appealing for teams that ship many product tests and need faster, cleaner decisions.
For Preply, Statsig is a natural fit for questions like:
- Does a shorter learner onboarding flow increase first lesson bookings?
- Does showing tutor response time improve message rates?
- Does a new recommendation model increase long-term retention?
- Does discount messaging improve conversion without hurting gross margin?
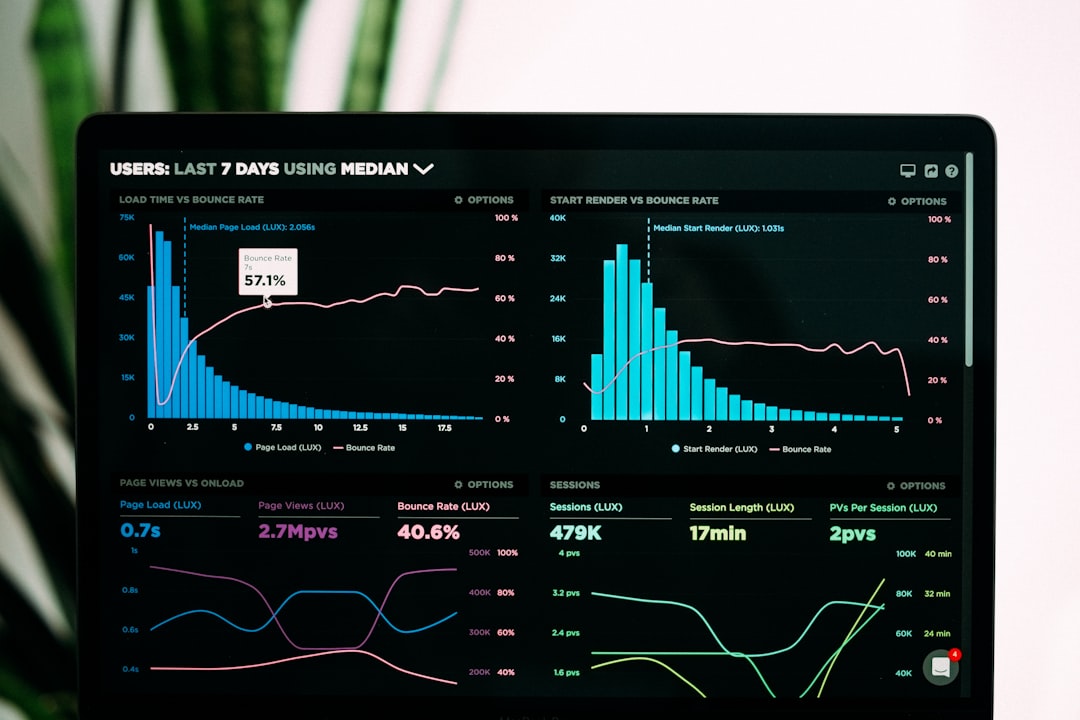
Statsig’s value is not just experiment setup. It is the analysis layer around the test. Serious experimentation needs sample ratio checks, exposure validation, metric definitions, confidence intervals, user segments, and guardrail reporting. Without that, teams end up arguing in Slack with screenshots from three dashboards. Honestly, that gets old fast.
Statsig also works well when the business wants a shared metrics catalog. A metric such as trial lesson booking rate should mean the same thing across growth, marketplace, and payments teams. If every team defines it slightly differently, A/B testing results become political instead of scientific.
What Preply should require from either tool
The vendor choice matters, but the operating model matters more. A poor implementation will damage trust in both LaunchDarkly and Statsig.
Preply should require these basics:
- Sticky assignment: a learner should not bounce between variant A and B across devices or sessions.
- Clear identity rules: anonymous visitor IDs, learner IDs, and tutor IDs must be stitched with care.
- Server-side decisions for critical flows: checkout, ranking, and pricing should not depend only on client-side logic.
- Exposure events: log when a user actually sees the tested treatment, not merely when they qualify for it.
- Guardrail metrics: monitor refunds, cancellations, support tickets, page latency, payment failures, and tutor earnings.
- Rollback paths: every risky feature needs a kill switch with a named owner.
It drives me crazy when teams celebrate a “winning” test while ignoring that average page load rose by 400 milliseconds. In marketplace products, those costs hide in support queues, churn, and trust. A reliable testing system must surface them early.
LaunchDarkly vs Statsig: practical comparison
| Primary strength | LaunchDarkly: feature release control | Statsig: experimentation and metrics |
| Best users | Engineering, platform, DevOps, release managers | Product, data science, growth, analytics, engineering |
| Risk control | Excellent for staged rollouts and kill switches | Strong when tied to guardrails and diagnostics |
| Experiment analysis | Useful, but not usually the deepest layer | Core product strength |
| Governance | Strong approvals, audit trails, targeting controls | Strong metric governance and experiment review flows |
If Preply already has a strong internal analytics platform and only needs safer rollouts, LaunchDarkly is a sensible choice. If Preply wants to scale experimentation across many product squads with consistent metrics, Statsig is more attractive.
Recommended architecture for Preply
A clean architecture should avoid scattered flag calls and mixed assignment logic. The safest approach is to create a thin internal experimentation service that wraps the vendor SDK. Product services call that internal layer, not the vendor directly from every codebase.
This gives Preply several benefits:
- Vendor flexibility: switching tools later becomes less painful.
- Consistent logging: every exposure event follows the same schema.
- Central privacy controls: user attributes can be filtered before leaving internal systems.
- Better reliability: defaults can be defined if the vendor SDK times out.
For critical paths, Preply should also define fail-safe defaults. If the flag service is unavailable, checkout should fall back to the stable experience. Tutor matching should not break because an experiment call failed. Latency budgets should be explicit, such as under 50 milliseconds for flag evaluation in user-facing flows.
When a hybrid model makes sense
Some companies use LaunchDarkly for release flags and Statsig for experiments. That can work, but only with discipline. The danger is duplicate assignment. If LaunchDarkly decides rollout eligibility and Statsig decides experiment variant, teams can misread exposure data unless both systems are linked carefully.
A hybrid model needs clear ownership:
- LaunchDarkly owns operational flags: kill switches, infrastructure migrations, permissions, staged releases.
- Statsig owns experiment assignment: A/B variants, holdouts, metric reads, and experiment results.
- The data platform owns truth: revenue, bookings, refunds, retention, and tutor-side outcomes.
Without that split, expect to waste time on mismatched numbers. One dashboard says the test has 120,000 exposed users. Another says 96,000. Then the real work stops while people debug event definitions.
Final recommendation
If Preply must choose one platform for safer experimentation, Statsig is the better default. It aligns more closely with A/B testing, metric governance, and decision quality. That is where most experimentation programs fail.
If Preply’s main pain is release risk, LaunchDarkly is the better default. It is mature, controlled, and well suited for engineering-led rollouts across web, backend, and mobile systems.
The best answer depends on Preply’s current weakness. If teams ship safely but argue about results, choose Statsig. If teams measure well but fear breaking production, choose LaunchDarkly. If both problems exist, use a hybrid setup, but keep assignment rules and metric ownership painfully clear.
Safer experimentation is not about running more tests. It is about making better product decisions without damaging learner trust, tutor income, or platform stability.